Controller Failover
sind can run Slurm’s active/passive controller setup: a primary slurmctld on controller and a backup slurmctld on controller-backup. This guide shows how to create the pair, check which controller is in control, and trigger a failover gracefully or by simulating an outage.
Create a cluster with a backup controller
kind: Cluster
name: dev
nodes:
  - role: controller
    backupController: true
  - role: worker
    count: 2
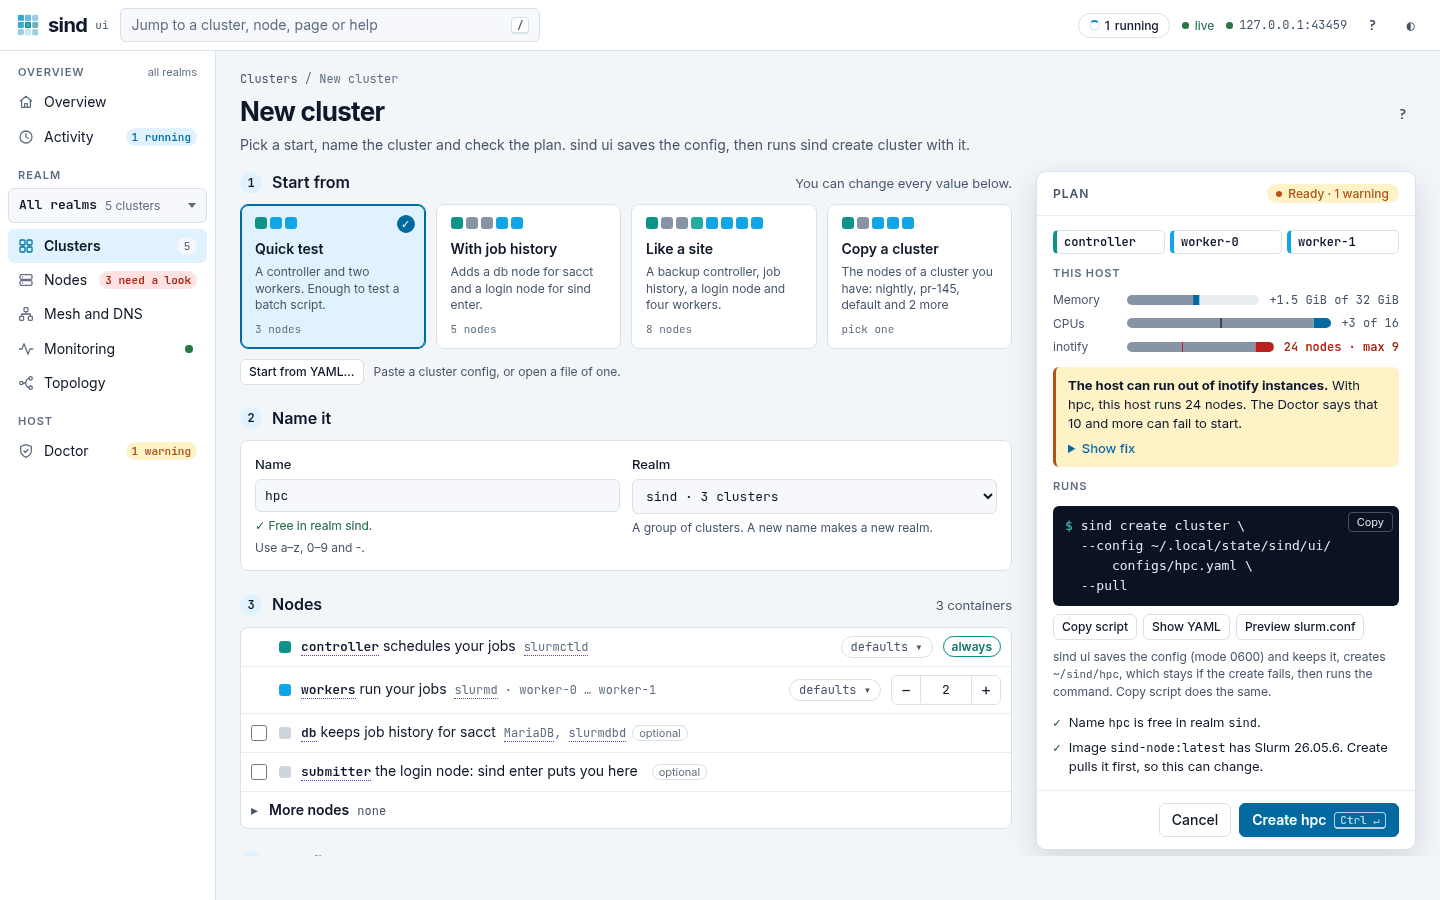
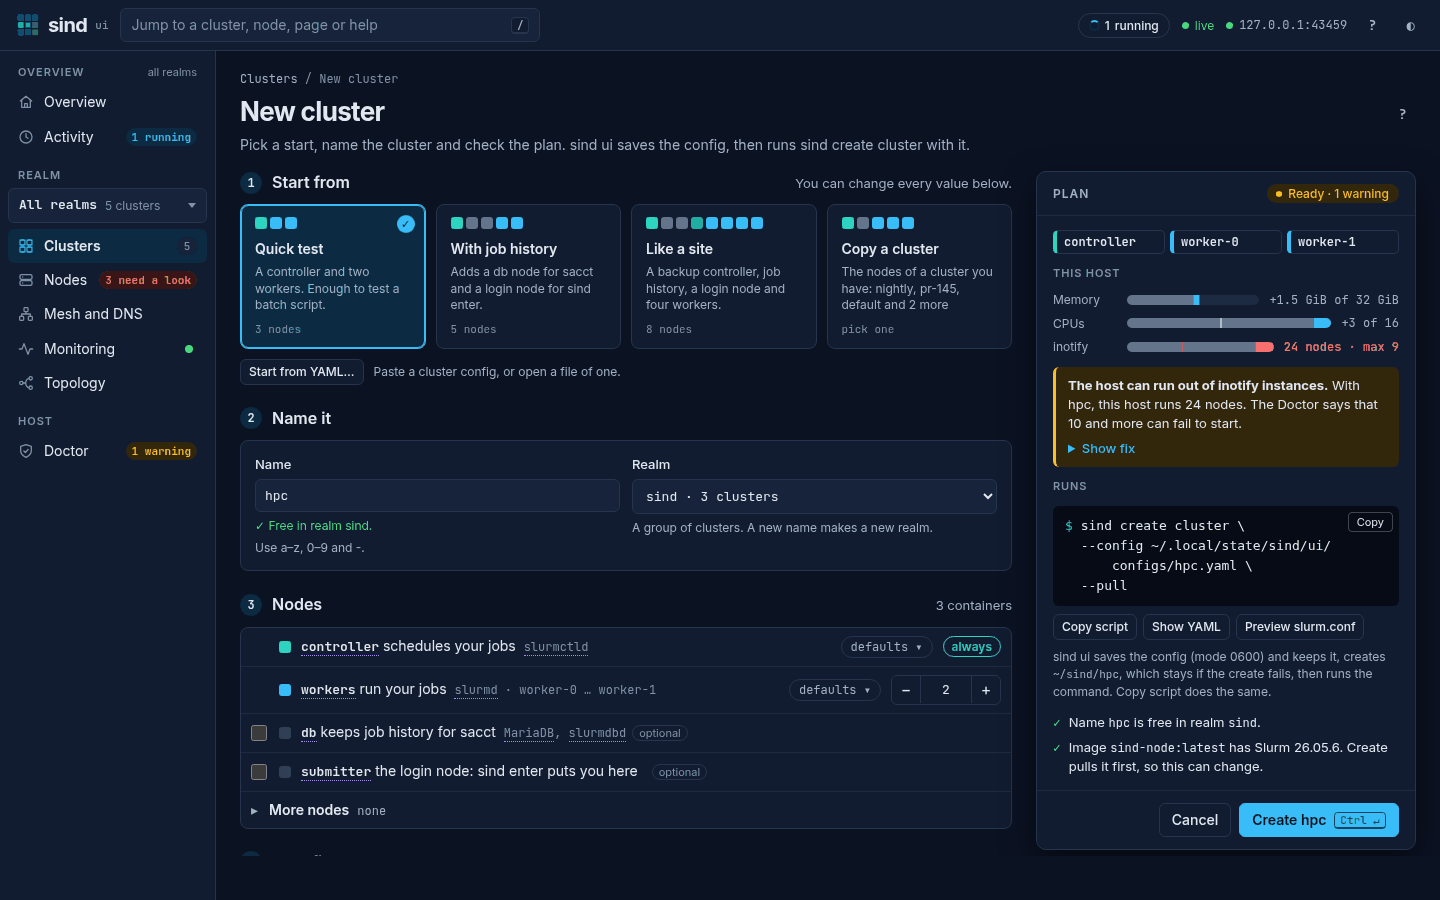
sind create cluster --config ha.yaml- Press New cluster… and set the name to
dev. - Open More nodes below the nodes and tick backup.
- Press Create dev.
sind then:
- creates
controller-backupnext tocontroller, with the same image, resources, volumes, capabilities, devices and security options - writes both hosts to
slurm.conf(SlurmctldHost=controller, thenSlurmctldHost=controller-backup) and setsSlurmctldTimeout=20 - mounts a shared state volume,
<realm>-<cluster>-state, at/var/spool/slurmctld(StateSaveLocation) on both controllers - starts
slurmctldon both; the backup waits in backup mode and takes over when the primary stops responding forSlurmctldTimeoutseconds
sind create cluster waits until both controllers answer scontrol ping.
To change the takeover delay, set SlurmctldTimeout in the main section:
slurm:
  main: |
    SlurmctldTimeout=10
SlurmctldHost and StateSaveLocation are generated for the pair and cannot be set in slurm.main.
Check which controller is in control
sind get cluster adds an HA column for the pair. It shows each controller’s position, and * marks the one in control:
NODES
NAME                   ROLE        HA        IP          STATUS   SERVICES
controller.dev         controller  primary*  172.19.0.2  running  munge ✓ slurmctld ✓ sshd ✓
controller-backup.dev  controller  backup    172.19.0.3  running  munge ✓ slurmctld ✓ sshd ✓
worker-0.dev           worker      -         172.19.0.4  running  munge ✓ slurmd ✓ sshd ✓
With -o json, each controller’s health carries "ha": {"position": "primary", "in_control": true}. sind get node controller-backup.dev shows the same information for one node.
sind reads this from the heartbeat file the controller in control writes to StateSaveLocation. A controller counts as in control when it wrote the heartbeat within the last 60 seconds and its own slurmctld answers scontrol ping.
From inside the cluster, scontrol ping reports whether each slurmctld is up:
sind exec dev -- scontrol pingSlurmctld(primary) at controller is UP
Slurmctld(backup) at controller-backup is UPGraceful failover
Ask the backup to take over:
sind exec dev -- scontrol takeoverThe backup takes control and the primary’s slurmctld stops. Running and pending jobs are kept because both controllers share the saved state. sind get cluster dev then shows backup* and slurmctld ✗ on controller.
Hand control back by starting the primary’s slurmctld again. On start, the primary tells the backup to return to backup mode and takes over:
sind ssh controller.dev -- systemctl start slurmctldFailover by outage
Use power control to simulate the primary failing. The backup takes over once the primary has been unresponsive for SlurmctldTimeout seconds.
| Scenario | Command | Recovery |
|---|---|---|
| Host crash | sind power cut controller.dev |
sind power on controller.dev |
| Clean host shutdown | sind power shutdown controller.dev |
sind power on controller.dev |
| Hung controller | sind power freeze controller.dev |
sind power unfreeze controller.dev, then sind ssh controller.dev -- systemctl restart slurmctld |
| Daemon crash | sind ssh controller.dev -- systemctl kill -s KILL slurmctld |
sind ssh controller.dev -- systemctl start slurmctld |
When the primary’s container starts again, systemd starts its slurmctld, which reclaims control from the backup. A frozen primary resumes without knowing that the backup took over, so restart its slurmctld after unfreezing it to hand control back cleanly.
Watch the takeover and the logs of either controller:
watch sind get cluster dev
sind logs controller-backup.dev slurmctld --follow
While the backup is in control
sind enterandsind execrun on the controller in control when the cluster has no submitter.sind create workerandsind delete workerupdatesind-nodes.confand reconfigure Slurm through a running controller, so they keep working while the primary is down. With both controllers down, they refuse to add or delete managed workers.sind ssh controller.devandsind logs controller.devstill address the primary container by name.
To run a pair whose Slurm configuration you provision yourself, see Unmanaged Cluster.