Worker Management
Add workers
sind create worker [CLUSTER] [FLAGS]- On the page of the cluster, press Add workers…. From the Overview or the jump box, with several clusters, the dialog first lists the clusters by realm with their health and workers: pick one. Change… goes back to the list.
- Set How many. Leave CPUs and Memory empty to take the values of the newest worker. The dialog shows the size and the names of the new workers, such as
3 × 2 CPUs, 1 GiB: worker-6 … worker-8. - Check the host: a bar sets the memory limits of the nodes that run now, in every realm, and of the new workers against the memory of the Docker host. Above 80 % the dialog warns. When the limits come to more than the host has, How many says how many more workers fit, and the button stays off until you tick Add anyway. It also warns when the nodes reach the inotify limit that
sind doctorreports. - Press the button, such as Add 3 workers. The strip of the task dock shows the progress of the run.
The new workers join the partition all; your own PartitionName lines do not change. sind then runs scontrol reconfigure, and running jobs go on.
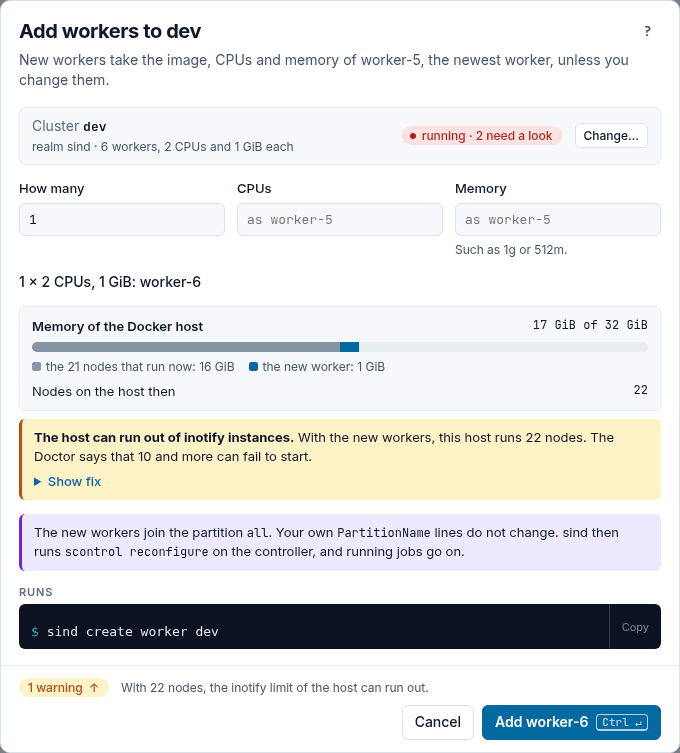
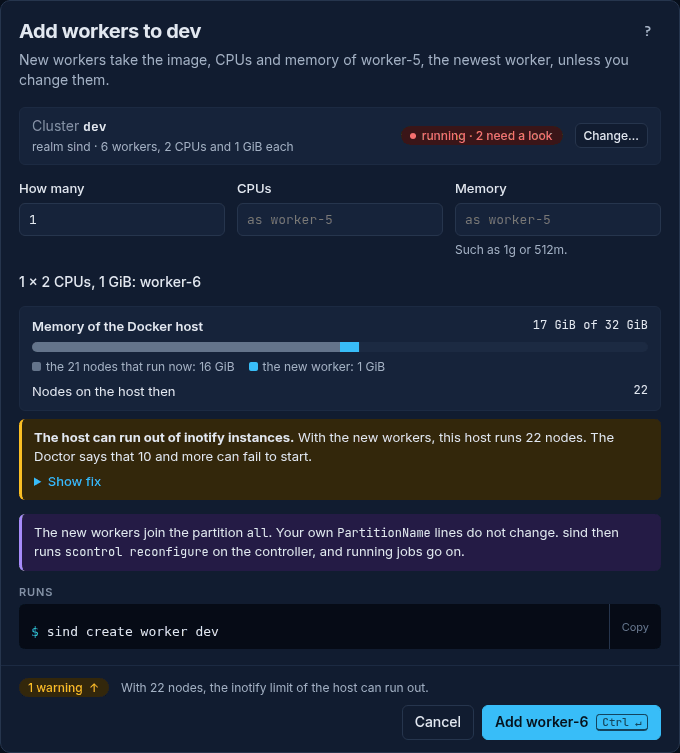
| Field | Flag |
|---|---|
| How many | --count |
| CPUs | --cpus |
| Memory | --memory |
The dialog sets no other flag. For the other flags, copy the command from the Runs line, add the flags, and run it in a terminal.
| Flag | Default | Description |
|---|---|---|
--count |
1 |
Number of nodes to add |
--image |
the newest worker’s image, else the controller’s | Container image |
--cpus |
the newest worker’s, else 1 |
CPU limit per node |
--memory |
the newest worker’s, else 512m |
Memory limit, without swap; it covers the node’s services and /tmp files too |
--tmp-size |
the newest worker’s, else 256m |
/tmp tmpfs size, part of --memory |
--unmanaged |
false |
Don’t start slurmd, don’t add to slurm.conf (implied on unmanaged clusters) |
--pull |
SIND_PULL, else false |
Pull the --image once before creating containers; needs --image, and without one sind does not read SIND_PULL |
--wait |
SIND_WAIT, else 5m |
How long to wait for the new workers to become ready, counted from when their containers have started; 0 for no limit |
--cap-add |
the newest worker’s, else none | Add Linux capability (repeatable; e.g. SYS_ADMIN); --cap-add= for none |
--cap-drop |
the newest worker’s, else none | Drop Linux capability (repeatable); --cap-drop= for none |
--device |
the newest worker’s, else none | Expose host device (repeatable; e.g. /dev/fuse); --device= for none |
--security-opt |
the newest worker’s, else none | Security option (repeatable); --security-opt= for none |
New workers take the indices after the highest one in the cluster: with worker-0 to worker-5, --count 3 adds worker-6 to worker-8. A gap left by a deleted worker is not filled.
Defaults from the newest worker
New workers look like the cluster’s newest worker: the one with the highest index among the workers managed like the new ones, or among all workers if none is. sind reads its image, CPU and memory limits, /tmp size, capabilities, devices and security options from Docker, so sind create worker on a cluster created with cpus: 2, memory: 1g or capAdd: [SYS_ADMIN] and devices: [/dev/fuse] adds workers with the same settings, and the same CPUs and RealMemory in sind-nodes.conf. Each flag you give replaces the inherited value; --cap-add, --cap-drop, --device and --security-opt replace the whole inherited list. Give one empty to add workers without any, e.g. sind create worker --device= on a cluster whose workers have /dev/fuse. An empty --image, --memory or --tmp-size is a usage error, so that an unset variable in --image "$IMAGE" does not quietly add workers like the newest one.
Not inherited:
- the security options that sind gives every node, and the
SYS_NICEcapability where sind gave it to a managed worker fortask/affinity(see Capabilities and devices), as sind decides them for each new worker. ASYS_NICEyou asked for yourself, with sind’s defaultTaskPluginor on unmanaged workers, is inherited; - a seccomp profile, which Docker reports by content rather than by file: pass it again with
--security-opt seccomp=FILE. sind says so in aWarning:line when it leaves one out.
A cluster without workers gets the controller’s image and 1 CPU, 512m memory and a 256m /tmp.
Image and Slurm version
Without --image, new workers run the image the newest worker (or the controller) runs, by its ID: the tag it was created from may since point to another image, even another Slurm release. --pull therefore needs --image.
With --image, sind pulls the image once if the daemon does not have it (with --pull in any case), runs slurmctld -V in it, and refuses managed workers whose Slurm version is not the cluster’s: slurmd must not be newer than slurmctld. To add workers from a moved tag, name the cluster’s release, for example --image ghcr.io/gsi-hpc/sind-node:25.11.9.
Before it creates a worker container, sind checks that the Docker host still mounts cgroup2 with nsdelegate, in a throwaway container of the controller’s image, as sind create cluster does, and fails with the commands that enable it otherwise.
Checks
--count must be at least 1 and --cpus must not be negative. --cap-add and --cap-drop take the capability names the cluster config’s capAdd and capDrop accept, --device needs an absolute host path, as devices does, --security-opt an option Docker knows, as securityOpt does, and --memory and --tmp-size take the sizes memory and tmpSize take (see Defaults section). sind rejects these, and --pull without --image, with exit status 2 before it creates any container. With -v, it logs the extra privileges of the new nodes, as sind create cluster does.
Workers that would not fit on the realm’s mesh or the cluster network, Docker bridge networks of at most 1,023 containers each, fail with exit status 1 before sind creates any of them (see Limits).
Examples
# 1 managed worker like the newest worker
sind create worker

# 3 managed workers
sind create worker --count 3

# Workers in a named cluster
sind create worker dev --count 2

# With resource limits
sind create worker --cpus 2 --memory 1g

# Unmanaged workers (slurmd not started)
sind create worker --count 2 --unmanaged
Managed worker workflow
For managed workers (the default), sind:
- Creates the worker container(s)
- Adds node definitions to
sind-nodes.conf - Reconfigures slurmctld (
scontrol reconfigure) - Starts slurmd on the new node(s)
This requires a running controller and sind-nodes.conf in /etc/slurm. If you replaced the generated Slurm configuration, use --unmanaged instead. If the controller is stopped or frozen, sind fails with an error that says so: run sind power on or sind power unfreeze on it first.
If a step fails, or you interrupt the command, sind removes the new containers again and writes back sind-nodes.conf as it found it, so you can simply retry. If that cleanup fails too, the error says so after the original one.
On an unmanaged cluster, every new worker is unmanaged, with or without --unmanaged.
If a new worker is not ready within --wait, or its munge or slurmd unit fails, sind create worker fails with exit status 1, names the worker and the check that failed, and removes the workers it created, as sind create cluster does (see Cluster Lifecycle).
Remove workers
sind delete worker NODES- Open the cluster, then the Nodes tab.
- Select the workers. The selection shows as a node set, such as
worker-[2-4]. - Press the delete button in the selection bar, such as Delete 3 workers…. If you selected other nodes too, it counts only the workers and deletes only them. The dialog lists what goes and what stays.
- Type the name of the worker when you delete one worker, else the number of workers, such as
3, in the field beside the button (its label says which), and press the button, such as Delete 3 workers.
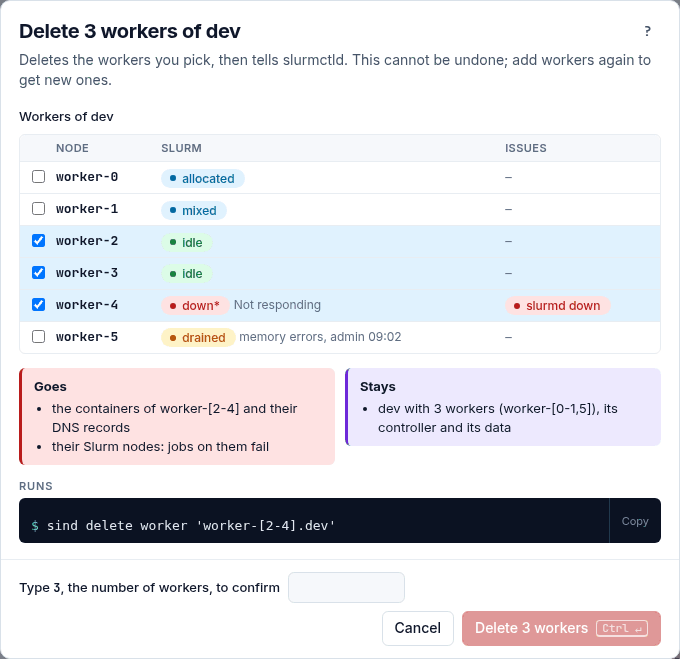
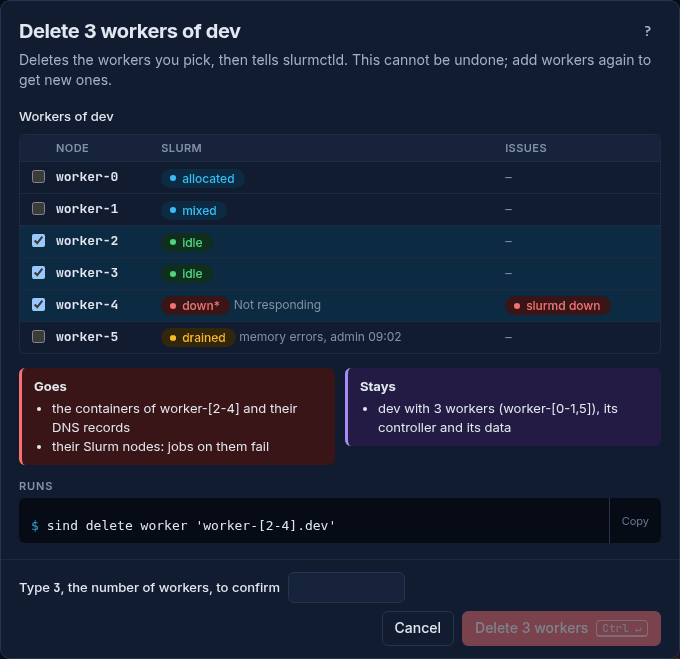
On the page of a worker, the ⋯ menu has Delete worker… too.
For managed workers, sind removes them from sind-nodes.conf and reconfigures slurmctld before deleting the container. Works with both managed and unmanaged nodes. On an unmanaged cluster, sind never edits the Slurm configuration.
Deleting a managed worker needs a running controller: with the controller stopped or frozen, sind delete worker fails and removes nothing, as the node would otherwise stay in Slurm’s configuration without a container. Unmanaged workers can be deleted at any time.
# Remove a single worker
sind delete worker worker-2

# Remove multiple workers
sind delete worker 'worker-[2-4]'

# Remove workers from a named cluster
sind delete worker 'worker-[0-1].dev'
With workers of several clusters, sind handles the clusters one after another, as sind power does. A cluster that fails does not stop the others: sind removes the workers of the rest, reports every failure and exits non-zero. The exported SSH configuration follows the workers that are gone, also after a failure.
See Node Arguments for the full node set syntax, set operators included.